WaPo on the many issues of LLM house writing styles. I have much to add. Here are some notes on applying a writing skill to override house style on Claude.
WaPo on the many issues of LLM house writing styles. I have much to add. Here are some notes on applying a writing skill to override house style on Claude.
You might call this a taste test: Obsessed with the story about the McDonald’s CEO and how his LinkedIn-style videos selling the McD’s franchise have escaped containment, leading to one of the funnier CEO/product marketing dynamics in recent history. Burger King’s CEO swooped in, holding widely-marketed listening sessions with customers and to demonstrate his love for the Whopper in contrast with the deeply weird McD’s videos. Must read: Internet long-hauler Katie Notopoulos on how direct-to-public marketing works when the public is more familiar with the product than the org’s leaders.
My teenager thinks fast food is cool and subversive (cue the sound of one hundred moms groaning) and she and her friends regularly talk shop. They are Taco Bell fans and think burger stops are kind of gauche. Not gauche: Baja Blast.
In the meantime, the fast food sector is becoming a playground for AI approaches, causing a lot of nervous discussion on social media and in tech spaces.
Apparently one thing LLMs excel at is deanonymization at scale. The original promise of pseudonymity online was social and normative, over and above any question of technical depth: decent people don’t try to unmask you, because why. What strikes me today is how what used to be unacceptably antisocial behavior online is now both automated and unremarkable.
Over the last couple of weeks, I asked a couple of chatbots what could be known about me from this pseudonymous site, where I am more intentional about what I choose to reveal and conceal. It pulled the obvious but also drew conclusions based on a few geographic points I’d made in context that were both revealing and correct. I also noticed that it only drew from the top two pages of information - anything beyond page two of posts wasn’t part of the compute. Archives are for humans?
People assume that there is some computer magic on the backend where the LLMs connect all your account logins behind the scenes, but no, in fact it does all this through inference, by linking your digital trail, your friends, your breadcrumbs of likes and hearts and follows, and obvs your posts, into a picture of who you are, practically and demographically.
Like Rickrolling on steroids: I didn’t even know P2P music file downloads were still a thing, but of course, and the scene had a big week recently when somebody trolled SoulSeek by generating a bunch of popular songs sung in Homer Simpson’s voice, then quietly polluted the platform by offering the AI generated Homer files up to other users. Someone then set up a digital radio station of all the Homer Simpson songs called D’oh Radio. Here’s more reporting from Gizmodo.
There is a long tradition of Simpsonifying things that go online, so this is the latest iteration. We observed Homer covers going viral on social in 2024 and 2025.
Second wavers in tech and engineering talked a lot about the “god trick” of presenting knowledge and information, particularly around math and science, in a way that suggests its objectivity is eternal, immortal, unknowable. Work by Safiya Umoja Noble and others extended this lens to Internet search and architecture, finding that the search algorithm was never neutral, instead it was a series of business decisions wearing neutrality like a costume, creating a customer service experience. LLMs take that same trick and compress it further.
It’s an old idea, and one I’ve been drawing from while I tinker with Claude, which is purportedly the best in the game. The “god trick” is baked right into the AI interface: one input, one output, an authoritative-seeming answer, offered without named perspectives behind it, trained on text produced overwhelmingly by a narrow demographic who has historically had access to both literacy and publishing, by programmers and new media drawing from the same well. Smushed together, it gives the impression that consensus exists where there are in fact many, many loose ends.
I increasingly find it annoying that even “good” AI outputs seem fixed on phrases like “key,” “core,” “exist,” “actually,” “never,” and possibly the worst sentence structure of all time, “it’s not X, it’s Y” — and I’ve begun to recognize how LLMs work like autocorrect for and idea, drawing from ranked search sources first before fanning out to more obscure sources, trying to determine and assert what’s important to me, a user known by demographics and data. It feels like a big linguistics machine, which is pretty cool in some regards, but also aggressive. The math doesn’t always work to connect me to what I want to find because I am situated in my individual context in ways LLMs are not able to understand, with my memory, in my body, with my unique experiences, which shape and translate meaning for me as I interact with the world (and the web).
And so for you, in your body and memory and experience. An LLM can approximate the outputs of an experience without having access to the experience itself. Sometimes this is useful, sometimes it’s reckless.
Overall the dynamic reminds me of the famous scene from Good Will Hunting: Claude is a smart kid, and he’s never been outta Boston.
New research shows that social media advertising suppresses voting in targeted communities, and is the first to quantify the effect of this kind of microtargeting on voter turnout.
My friend Dave Bangert has been a Midwestern reporter for thirty years, and began his own newsletter project after layoffs and mergers emptied his local newsroom. Now his 8000 subscriber project is a major influence in a Big Ten town that otherwise has a weak media market. In this podcast he talks about how it all works, what we lose as legacy media dries up, and what it means when your readers know exactly who you are, and you run into them in the produce aisle.
As a true blue Hoosier, here’s my hot take on the Chicago Bears moving to Hammond: no dunking on NWI.
I’m seeing a lot of disgust for Indiana in related Bears commentary that troubles me, especially the comments about NWI as a place of blight, beyond consideration or repair, obscuring the stakes behind a regional geography of race and class. Meanwhile, I am glad that people from Chicago suburbs have found occasion to think about their neighbors in Hammond and Gary. There is life outside of Schaumburg.
Indiana’s history as a state is thick with race and class problems, perhaps best captured in the old phrase calling it the “middle finger of the South thrust into the North.” That middle finger reaches right up and touches Chicagoland. Indiana’s policy approach to this dynamic is predictably toxic, having cleaved communities like Hammond and Gary from state investments and statehouse power. Indy loves business and it loves a chance to razz Chicago. Guess why.
“The Region” in Northwest Indiana is practically and functionally the south side of Chicago. You can drive from Gary through East Chicago and Whiting straight into Pullman and Bronzeville, without much marking a state line other than some signage and an iconic White Castle. But everything on the Indiana side of the line is governed from a statehouse that rarely considers them at all until there’s a chance to further demean and isolate them. Like so, with Indiana’s current plans for redistricting that further disenfranchise Gary residents.
Does it serve to remind us that Gary was founded as a company town by the world’s first billion dollar corporation? I think so (and great article btw). The town was the subject of serious curiosity and consternation during the early days of industrialization, especially when comparing the claims of the owners and capitalists to the realities of the workers. Poet Carl Sandburg famously wrote the poem “The Mayor of Gary” to illustrate the casual venality that the ownership class felt toward the steelworkers. This dynamic is still very much alive in the minds of the people in surrounding communities, who are perpetually worried about a “Chicago influence.”
This is why we train a jaundiced eye on characterizing working class communities like they’re beyond consideration or redemption. The world isn’t a Costco. People live among the brownfields. I spent a lot of time in this area in my twenties – all my friends in The Region were somehow connected to US Steel, even still. Feel however you feel about the Bears deal, but we don’t do Gary slander in this house.
Yanking this back to the question of writing: if you want to catch an interesting news source from the area, Capital B’s Gary outlet does some amazing reporting and opinion.
The last time I went truly viral was in April of 2020 in the height of the COVID shutdown. I posted a tweet and walked away from my phone. By the time I checked back, my notifications were out of control.
The next morning, I got a message from an old friend familiar with my handle. “I think I saw your account on Good Morning America?” Hilariously, there I was, and I couldn’t even claim responsibility for the meme.
I’ve spent most of my time on the internet as a pseudonymous account, using my first name only, or using a handful of handles (incl feministe, fauxrealtho, flotisserie, paired with punny names like “Petty White” and “Frieda People,” a convention from the Tumblr years). Even as a visible personality online, I was only known by my first name and URL and/or handle. In recent years I de- and reactivated some of my socials, so some of these breadcrumbs no longer exist, but I’ll do my best.
Pseudonymity allows writers to explore complex ideas in digital spaces while protecting their identity, location, and other identifying factors, while also maintaining a throughline of identity and storytelling.
There are a lot of trade offs in using a pseudonym, especially around how to claim credit for your work. But people use them because they give you the privacy to be honest, real, weird, authentic, and to escape the creep of modern social media presence into high stakes spaces like the workplace. This dynamic was kind of the impetus behind the era of “weird Twitter,” where people using pseudonymous social handles routinely threw out funny, absurdist one-liners to impress their friends and followers, while taking a turn at the social media slot machine. Not every post or joke lands in a way that converts to numbers, but some do, and it’s fun to try.
I’ve written a little previously about how the English program I was a part of used fiber arts to illustrate the fundamentals of technical writing, but one of their other methods of teaching the internet was through board games. Games, like the internet, and much like writing, provide rules and structure for communication and engagement, but everything that happens inside the container of game board and game play is a mystery until it emerges through human interaction. So goes the internet (and to some extent, so goes AI). Games and gaming were used as a method to think through what it means to create rules of play, then let a community rip through the model – and many of the thinking and skills involved around game design apply in social digital spaces, from chat rooms and Teams channels to the open seas of the WWW. The longer you’ve been playing the slot machine, the more you get a feel for the kind of thing that will get seen and read, and who among your readership will take your content to the next level.
Why does it matter? Because understanding what “works” to make ideas travel further online, the more you can tap into it. Big Tech is under fire right now for amplifying some of the worst impulses of the internet, by cranking engagement algorithms to exploit messages that produce outrage. Yes, big emotions create virality, but so do relatability and sharability.
So back to the meme: here’s how it went down.
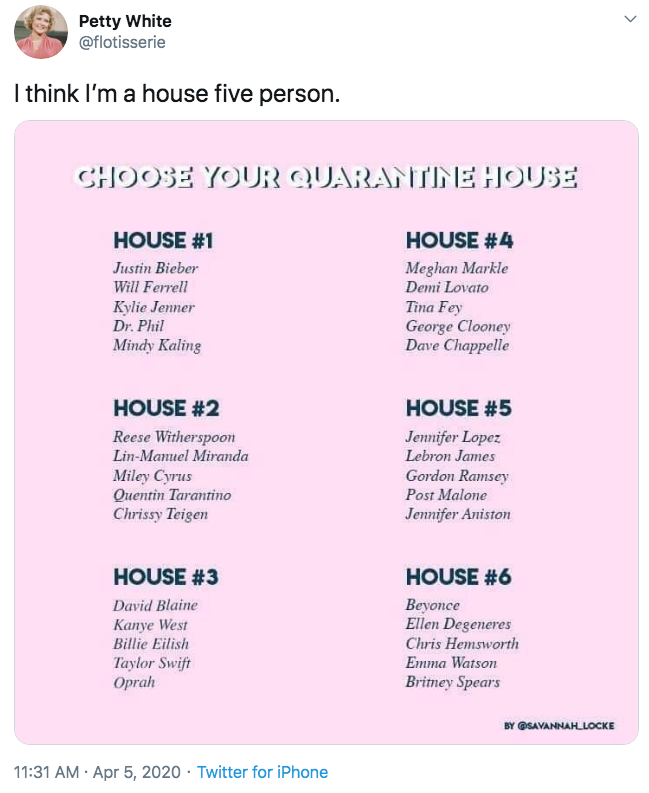
The meme was a list of six hypothetical celebrity households: pick one to quarantine in.
It had been circulating on Facebook, started by a Christian influencer named Savannah Locke. I encountered it deep in a Real Housewives fan group, and felt the pull of a good parlor game. In April 2020, everyone I knew was sitting at home, fretting about the COVID-19 pandemic looming over all of us, so I shared it with minimal ceremony, a couple of buddies with a slightly larger following hit retweet, and within two days the tweet was being cited by The Cut, Time, the Washington Post, ABC News, and others. Know Your Meme documented it for posterity. Several outlets named me as the originator, but trust, I was only trying to delight my friends with low grade Facebook content. I couldn’t find the original meme at the time – Locke appears to have had a name change that scrambled my search. But hey, as these things go, nobody earned a dime or promoted anything weird, so no harm, no foul. Business Insider managed to credit it correctly, so a special kudos to their editor.
The core game mechanism behind the meme is forced choice: constraints generate opinions and opinions generate activity. Each “house” also represents a personality type. House 3 is chaos, House 6 is aspirational, House 5 is the one where someone is definitely cooking and someone is definitely yelling about it. The choices are arbitrary, which invites curiosity about who grouped what and why. In short, this meme offered a light conversation starter at the right time, with low stakes, high personal reveal, and endlessly discussable combinations. It also drew from existing memes and games that are popular online, like “where you sitting” in the proverbial lunch room. This one became news because of the timing and gamability, not because I was particularly clever, but hey.
What does it feel like to go so viral? It’s hilarious, strangely affirming, and also a little crazy-making. It opens the door to a whole lot of wild people and ideas on the internet, not all of them flattering or welcome. Virality is sometimes paired with incredible harassment and requires “more condolences than congratulations.” But as far as this particular experience went – hilarious, whoops, and wow. It just felt like a Lebron James, Post Malone and Jennifer Aniston hang would be a good time.
In an Internet of things (IOT), what happens when the companies behind the service model cease to be?
What to do when the biggest platforms for readers are kind of evil?
“Because RSS is an open protocol, and because there are so many different possible ways to follow and read the news, RSS readers ought to be a UI playground in the way Twitter clients once were, where innovation and experimentation are normal and celebrated.”
There are many hyperbolic essays on AI going viral this week. This essay gets into some of the emerging politics around AI in the United States and how they map onto electoral politics, and is irritated with the American left’s approach to AI.
I agree on one angle, that as a cohort, abstaining entirely from new tech is a bad approach.
Haraway (obvs) suggests we stick with the trouble, that sometimes our very presence in the room is what’s required to trouble existing narratives, and that it’s important that share what we learn back to our people at home, whatever that means in our context.
For me: I spend a lot of time at work translating technical ideas and projects in an institutional voice, but on nights and weekends, I’m explaining the ins and outs of the internet to my working class friends and family. Increasingly, I’m asked to explain LLMs and AI and how it relates to their needs around business, the news, entertainment, and as a legal aid.
The “cyborg’s mark” is a metaphor for writing, our duty to translate, and the inevitability of translation through experience. Perhaps staying with the trouble allows us to articulate our experiences in and around the science in ways that both advance our interests and that keep our communities safer. For those of us who straddle multiple worlds, translation is a responsibility.
Widespread AI adoption reopens some basic questions in business: who your audience is, what work can reasonably be automated, what absolutely requires human oversight, and how the service and information environment actually holds together when we shuffle these circumstances around. All this, with many social and environmental risks and a side of existential doom.
The hype makes it harder to see a change that’s already here. To me, the shift between SEO to GEO is one of the clearest places where a change in technology produces a significant process change in the relationship between a writer and an audience, with all the tradeoffs around authority, context and information architecture that implies. But web search is just one place this shows up.
I suspect the predictions of economic and social doom are overblown by a lot – in life as in business, generalisms are easy and specifics are hard. Last mile issues remain a reality of nearly any technical or software implementation, and differentiation is in many ways the art of business. There are serious incentives to promising a smooth, profitable near-future, especially around emerging markets, so I feel pretty comfortable forecasting that the era we currently live in is valuation masquerading as value. Instead, I think we should worry more about how the tech changes our relationship to information and to each other.
I’ve been writing about how writing and code are the same thing in digital environments, and about how that equivalence shaped the early web. AI changes that relationship.
The dominant conversation is about whether LLMs can write well, but I suspect that’s the wrong frame. Human storytelling will probably always be more interesting than generated storytelling, because humans love quirks and novelty that can’t be produced artificially.
The more consequential change is that AI-generated text doesn’t just sit on the web waiting to be read, and instead feeds back into the system that produced it. It becomes training data, source material, and eventually, architecture. Remember: When an LLM generates text, it’s producing word sequences based on statistical patterns. The output is one plausible version to your prompt, not a definitive one — but it gets indexed, linked, and cited like any other writing. Nothing about its surface tells you it doesn’t carry the same authority.
Researchers call what follows “model collapse,” a feedback loop where models trained on AI-generated content lose touch with the range of human-produced data. The rare and specific details disappear first, then the middle narrows. Eventually what’s left is smooth, confident, increasingly generic text that sounds authoritative whether it’s accurate or not, which becomes the training data for the next round.
I’m thinking about it in terms of the shift from SEO to GEO. SEO preserved a connection between writing and human judgment. Someone wrote content, search engines indexed it, readers got a list of links and decided which to trust by comparing to their own experience and knowledge. This system was gameable through various sleights of hand, but it assumed a reader with agency. The creator’s job was to be easy to find and worth finding. Streaming video complicated this process but still worked with the same basic ideas. Meanwhile, GEO operates on a different premise. The goal isn’t to get found by a person, but to be found by an algorithm assembling a response the user may or may not independently verify.
(Sad news: today, only about 8% of LLM users verify their output against source material.)
(This does not bode well.)
Consider what happens to the same piece of writing in each system. In the SEO world, your article gets indexed, shows up in search results, someone clicks through, reads it, evaluates whether you or your institution is credible on the topic, maybe skeets it or sends it to a colleague. A human encountered your work, weighed it and decided it was useful, the algo responds and indexes accordingly.
In GEO, an AI system parses that same article, extracts the most clearly structured claims, and drops them into a synthesized answer alongside fragments from other sources the user never sees individually. The reader gets a confident, blended paragraph.
In the old way, the reader moved through the web. AI yanks that experience into a single response from a single interface. We don’t fully understand how AI systems decide what to cite, which makes this power shift feel especially risky. Worse, different people will get different responses from LLMs, even using the same prompts and source materials. We don’t know why.
Fewer entry points to the web means fewer opportunities for diverse or unexpected sources to gain traction, which means the training data gets narrower, which means the outputs get more generic, which means the architecture narrows further, which means fewer perspectives represented in the output. For the reader, it accelerates context collapse in much the same way. Fewer inputs means fewer opportunities to stress test your ideas against new information.
So, what to do?
If generative AI grows as predicted, SEO and GEO will coexist for awhile, and working developers and communicators will need to understand both and how they layer. Strong SEO foundations give you a great head start in AI visibility too, so the fundamentals of good writing and web taxonomy still matter a lot.
But the production of knowledge, the keeping of data, and how it’s all indexed are subjects that are about to become very important, and very political. So I suspect that any fields that touch those topics will also become very important, and very political, very soon.
When I started building websites in the late ’90s, the line between writing and coding didn’t really exist. A person probably learned HTML because she had something to say and needed a place to put it. The internet was free and anonymous and it felt audacious to put your stuff online, like flinging a message in a bottle out to sea. The code was a container for the ideas that rendered them onscreen, and every post and page you published was both a piece of your thinking and a brick in something larger.
People forget that the early web was a writing community. Writers, or bloggers, built their own sites, maintained their own archives, linked to each other deliberately. A blogroll was both a reading list and a show of solidarity, a trackback was a way of saying, “I see you, I’m thinking with you.” The technical architecture - RSS feeds, permalinks, comment threads - existed to organize the writing and the writers’ thoughts, and to push their ideas forward on the open web.
This worked for a time. Communities of writers, most of them without institutional backing or media credentials, built new bodies of knowledge together through interacting as readers and writers, communicating across a foundation of code. The work didn’t stay online. It spilled into conference halls and state houses and newsrooms and policy discussions. As the body of communication built, it created something that accumulated over time. These people influenced mainstream journalism, shaped public conversations, launched careers and movements. In many ways, the national political conditions we face today are a reaction to that movement, and how it allowed regular people to influence the world through the democratization of mass communication.
Midway through the aughts, the brick and mortar publishers and venture capitalists started looking across the landscape, at all the writers creating fantastic content, largely for free, and sucked them into their content and editorial teams. Google Reader lost institutional and financial support as writers moved off the open web and onto publishing platforms, often backed by VC money, that measured the quality of your work by engagement. The addition of algorithmic feeds further broke down this structure – the algorithm doesn’t measure whether your work contributed to shared understanding, but whether it generated a click, a share. The code changed, and the writing changed with it.
The writers changed with it, too. The blogger became the influencer. Bloggers operated in a gift economy of ideas: you wrote to think, to argue, to contribute, and your standing in the wider community came from the quality of your work and contributions over time. Was it a meritocracy? No, but the conditions made it possible for a regular person to talk with experts as peers, which upended traditional power structures around authority and expertise (in both directions, good and bad). Meanwhile, influencers operate in a heavily capitalized attention economy where engagement converts to dollars. The audience is a market to press for money.
The gendered dimension of this shift matters as well. The early blogosphere was full of women writing sharp, rigorous work about politics, culture, parenthood, identity, and technology — work that was explicitly feminist and anti-racist and genuinely moved public conversations. This was the community I helped build (Feministe.us was my project, a community platform of writers and commenters whose coverage and discussion broadly fell under, but was certainly not limited to, the topic of feminism). When the monetized platforms absorbed that energy, the commercial model recast women’s online authority almost entirely in terms of consumer influence. What could we sell? And to whom? The framing around our work went from “this person has important ideas” to “this person can sell things to a niche market.” Meanwhile, men who’d built audiences through tech or political blogging were more likely to be absorbed into mainstream media as columnists and analysts, roles that kept their intellectual authority intact. The influencer label, with all its connotations of superficiality, landed disproportionately on women, and it stuck.
There’s a class piece here, too. The platform model offered something the early blogosphere mostly didn’t — a way to get paid. For women who’d been doing enormous amounts of unpaid intellectual labor building online communities, the question of monetization wasn’t shallow. The implications of information centralization and monetization were as present then as they are now with LLMs and AI. Some people figured out the social platforms and worked their way into viable digital careers. Platforms offered a lot of perks, but all of the perks had a backstop. Corporate interests introduced the problems of advertising, audience and sponsorship, which meant reorienting your individual practice around maximizing your commercial value over and above your intellectual contribution and community management skills. It often meant giving away some or all of your IP rights.
For most people, new system didn’t offer a viable way to get from “respected independent writer” to “respected, protected and compensated writer.” Many of us found ourselves in positions too precarious to take the leap into freelancing and social media, and some, like me, got regular jobs doing regular stuff. Some married money. And in the meantime, some folks figured out how to get into real journalism, which looks much different in 2026.
Great storytelling helps people understand themselves and their world. We let some of that depth go on the Internet with the onslaught of digital marketing and all of its implications, and today the internet feels less useful and less trustworthy than it once did.
It feels like there’s something to take forward from the experience.
I’ve been running a series of informal experiments with my team to understand how we should advise people on using AI tools like ChatGPT, Claude and Gemini around our work.
In our last session, I gave everyone the same task: ask your AI tool to summarize a single article in plain language. Every person got a factually accurate summary, but the style and depth of analysis varied widely from person to person. We tested this further by entering the same prompt multiple times. Each time, the output was slightly different. We copied and pasted everything into a shared document so we could compare side by side.
Later that day, I asked everyone to reopen the tool they’d used that morning and repeat the prompt that had worked best: summarize this article in plain language. The outputs shifted again. Some changed dramatically. One team member whose morning summary had been light and conversational received a much more formal, serious version in the afternoon.
I then asked Claude to compare the morning and afternoon versions of one summary. “In short, the morning version emphasizes practical implications and accessibility; the afternoon version prioritizes completeness and specificity. They complement each other well — someone reading both would get a fuller picture than either one alone provides.”
Why would Claude produce these differences despite the same source material and prompt?
I asked the source.
Even with the same prompt and source material, LLMs don't produce identical outputs each time. This is by design — there's a degree of randomness (called "temperature") in how the model selects words, which means each run produces a slightly different path through the text.But the differences here go beyond random word choices. The morning version landed on a journalistic structure while the afternoon version landed on an academic one. That likely reflects what the paper calls sensitivity to framing and order effects — one of the cognitive biases it catalogs. Small, invisible differences in how the model’s internal processing unfolds at the start of generation can cascade into meaningfully different organizational choices. Once the morning version opened with a news-style framing, the rest followed that pattern. Once the afternoon version opened with a descriptive academic tone, it followed that thread instead.
This is actually a concrete example of the robustness issues the paper identifies. The underlying reasoning about the paper’s content is consistent across both summaries — neither gets the facts wrong. But the presentation varies in ways that weren’t requested, which means someone relying on just one version would get a subtly incomplete picture depending on which run they happened to see.
It’s a useful reminder that LLM outputs are one plausible version of a response, not the definitive one.
It’s important to understand how these tools work. What looks like an authoritative answer is really just one of many possible outputs the system could have generated. The text will sound plausible whether it’s accurate or not, and you may get different results each time you ask.
My undergrad experience in college really shaped my approach to the internet. I was an English Education major at the time, in the early 00s, when the internet was around but mostly the wheelhouse of scholars and nerds. I was a nerd, learning code as a vehicle for writing, primarily to amuse myself and my friends.
The English department was an embattled unit within a school within a college of a STEM-centric university whose administration was perennially annoyed by the Humanities and their writing requirements. One of the English department’s survival tactics was to grow their approach to technical writing, getting deep into the question of how technology changes, shapes and shifts reading, writing and literacy. Thus they organized loosely around an emerging field called “digital rhetoric.”
For a time this was the top rhetoric and composition program in the field, populated by scholars from scrappy programs. My closest mentor, an English PhD from Wayne State in Detroit, studied race and gender representation in video games and how programmers (particularly Black and trans programmers) write themselves into existence through code, design and other aesthetic and storytelling choices. Outsiders had a really hard time understanding how this work belonged in an English department, but ultimately, she was focused on the question of authorship and how the author is projected throughout her work, a classic literary debate. She treated video games as texts and gamers as an audience, an approach that foretold many things about our current political era.
In this space, “digital” doesn’t just mean content on a screen. The concept is more complex, including social, cultural and rhetorical dimensions, in addition to shifts through time. Digital “texts” and practices exist on a continuum with print and other media, rather than in isolation, transforming how persuasion and communication work, both separately and together.
I took all these lessons and ran with them. This is where my approach to the internet is situated, and there are a few truisms that I learned from that time and era that further position my writing and approach.
Writing and code are fundamentally the same thing in digital contexts. Both are systems of symbols that create meaning and action through semantic rules. The line between “content” and “container” blurs in digital spaces. A blog post is the copy on the page – and it’s also the metadata, the responsive design that adapts to different screens, the accessibility markup that makes it readable by screen readers. Each of these elements is written (coded) and each carries rhetorical weight and communicates something to the audience, intended or not. If you understand these relationships, you understand how the internet works as a social and information system.
This convergence of digital and material amplifies the concept of intertextuality, the idea that all texts reference, respond to and build upon other texts. In the classroom, intertextuality often focuses on plays and novels, and explores how authors speak and refer to one another’s work over time. In music, this is the study of sampling and referencing and why.
In digital environments, intertextuality becomes literal and functional. Code libraries reference other code libraries. Websites link to and embed other websites. APIs allow different platforms to communicate and share data. A single digital text might pull content from multiple sources simultaneously – a Twitter embed, a YouTube video, a Google Map – creating a networked document that exists across multiple platforms and authors. Virality builds rhetorical velocity through layers of meaning being added by individual users in real time, creating new texts and contexts through iteration and sharing.
Knitting patterns are technical writing in its purest form. A pattern is a set of instructions that must be precise, unambiguous, and reproducible, the same goals as any technical document. Pattern writers use specialized notation (K2tog, SSK, yo) that functions like code, compressing complex physical actions into standardized symbols that individuals interpret using sticks and string. The pattern must account for different skill levels, anticipate common errors, and provide enough context for the knitter to understand not just what to do, but why.
Good instructions and an able translator may result in a wearable delight: a sweater, a scarf, a cozy and colorful pair of socks. When a pattern fails the result is the same as failed technical documentation: confusion, wasted time and an unusable product. Piles of string. Dumb, useless sticks. It is an incredibly strong reminder that technical writing isn’t confined to manuals and protocols. It exists anywhere complex processes need to be communicated clearly and consistently so others can replicate results – including in your granny’s yarn basket.
So that’s how I learned to knit. Digital rhetors link physical practices to digital ones to illustrate highly conceptual ideas about writing and social networks. And one reason why digital spaces like Ravelry deserve recognition as thoughtful, functional social platforms is that this link between conceptual and material is made explicit in the digital knitting community. Designed for information sharing among a particular audience, decisions about information architecture and community management reasonably cascade from the mission, so Ravelry has remained a reasonably healthy community experience for most users despite its massive size and sprawling discussion. It remains an example of positive social dynamics online, unlike its behemoth competitors.
One major takeaway from Haraway’s work is the importance of rejecting binary thinking around technology and science. This approach aligns with other humanist and feminist perspectives that foundationally believe technology is by, about, and for the human experience, thus providing new and novel sites for political struggle. This gave people frustrated by tech a permission structure for interacting with technology rather than avoiding or abstaining from it entirely.
If these questions of knowledge and power remain central to technology, we want the people making those decisions to share our values and interests, and to be in the room when decisions are made. This argument is ripe for various challenges, which is why it was such a provocative starting point for cyberpunks and cyberfeminists alike.
We let public and private live alongside each other without rigid boundaries about professionalism and polish. Your serious professional work could sit next to a meme, which could sit next to a picture of your cat, and none of it diminished the other.
This was an intentional acknowledgment that people are multifaceted, and that the digital spaces we inhabit should reflect that complexity. Putting the personal and the real alongside the artificiality of digital communications builds a relationship between the viewer and creator in ways that carefully curated, brand-managed presences just can’t (also: yawn).
Vulnerability, humor, expertise, horror, scholarship, and joy coexist, as in real life.
I have a confession. While experimenting with AI over the last year, I wondered what would happen if I crammed an unfinished novel draft, one I actually care about, into Claude. Claude is pitched as the LLM for writers, with Claude 3.7 Sonnet and 3 Opus widely regarded as the premier LLMs for writers, including creative writing, long-form content and human-like prose. Meanwhile, I majored in English and work in mass communications, so I’m trained to think about writing creatively, strategically and tactically. Writing and personal expression have been part of my daily life for most of my life. If this tool could in fact produce a quality story, someone like me should be able to make it happen. Instead, the experience left me confident that AI isn’t a good vehicle for creative, narrative writing.
Here’s what I found:
On the technical side, Claude struggled to maintain a narrative thread over time. The longer the chat, the more the bot drifted and eventually lost track of details and claims made about characters earlier in the plotline. It’s not a sustainable approach for narrative writers because continuity matters: outsource too much plotline to the bot and your characters lose relationship to one another.
LLMs like Claude work fine for writing support—they can function something like a synonym machine, helping writers work through technical questions of redundancy, register, length, and other semantic needs while drafting. But when you outsource world-building and meaning-making to an LLM, it becomes narratively confusing fast. Despite giving Claude extensive background on my primary characters and the world they live in, it would confidently declare that a character’s relationship to another was X, then claim the opposite on the next page. Dialogue was thin and expository. It preferred a sort of “maid and butler” style of dialogue where two characters artificially recap shared knowledge for the reader. Meanwhile Claude does not do feelings well, which is arguably the point of much narrative writing.
Ultimately my drafts were worse off than what I started with – less organized, more confusing, with so much narrative drift that almost nothing was usable, even as a first draft. A devil’s advocate might argue that my prompting wasn’t sophisticated enough to produce the results I wanted. Sure.
But then we have the second problem: Claude’s approach to storytelling isn’t narratively interesting. Fiction and narrative writers put tremendous energy into world-building and sensory experiences. The goal is to immerse the reader in a sensory experience so total that they can experience another world entirely – the original VR, if you will. A great writer even exploits your higher-level cognitive functions by reusing parts of the brain that evolved for action and perception, which is why a good story makes you think, feel, and wonder.
Claude does not feel or wonder. Claude collates.
A key part of this essay suggests that LLMs create meaning through triangulation – that by pinging other ideas and vocabulary, an LLM can get a human reader close, or close enough, to suffice in many cases of writing. In my experience, this is true enough in business writing, where tinkering with approach and register can become as important as precise verbiage.
But this misses the pleasure and the point of good storytelling, which is myriad but usually centers on the satisfaction of expanding your imagination and experience through narrative, by seeing your own messy, striving, failing, hopeful, and collective human experience reflected in another person’s expression. That kind of meaning-making doesn’t happen through triangulation. It happens through the labor of human thought, experience and skilled articulation. That’s art, babes.
This article gets into the mess of AI and creative writing, within the domain of the romance genre, which famously cranks out variations on romance themes at a rapid clip. It drills down into some of the debates about writing, authority and authorship in relationship to LLMs that are playing out across the publishing sector now. Remember: early research suggests that most writers who use LLMs as part of their workflow ultimately retain their sense of authorship in and around the tools, suggesting that even when writers adopt AI assistance, they still see themselves, not the tool, as the creative and accountable source. So based in my experience above, I suspect that if an AI approach to creative writing is successful, it’s because the author is linking her approach to emerging tech, not because the work is good, and that’s a difference worth distinction.
🍿Watched: Toni Morrison: The Pieces I Am
This PBS doc recently came to Netflix, and I tucked in expecting a nice but predictably boring documentary about one of my favorite authors. To the contrary, it really plumbs Morrison’s writing craft, not only as an author but as an editor who brought a generation of incredible thinkers into the limelight. She talks in depth about her writing process, her approach to authorship and editing, and how she kept these roles separate at the peak of her midcentury literary career in NYC’s publishing industry.
There’s something so powerful about hearing her discuss the craft, her deliberate choices, the refusal to center whiteness, and the insistence that Black readers were her intended audience. She saw her critics and wrote around their critiques with authority and confidence. This was a breath of fresh air since I’m so immersed in the AI era, which threatens to change our perceptions around value of writing, the choices and experiences behind the author, and how we consider the influence and responsibility of authorship.
There is something about the AI moment that reminds me a lot of when the internet was new. A lot of what was imagined and promised about the internet was never realized. But much was.
I’ve been reading Ellen Ullman’s memoirs - “Life in Code” and “Close to the Machine” - and her observations about proximity to technology feel relevant here. Being close to the machine means understanding its actual capabilities and limitations apart from the prevailing sales narratives. It also means a kind of loneliness, because you are working in a space that others don’t yet see clearly or fully understand.
I suspect people thinking seriously about AI right now will experience something similar: a stretch of hostility and discomfort while the rest of the world catches up and the consumer market level-sets on the promises being made. In the interim, the hype will not match the reality, and the reality will sometimes exceed the hype in ways no one predicted. And for a while, how it works and why it matters won’t be legible to everyone at once.
In 1999, academic and theorist Judith Butler famously won an award for the worst academic sentence, raising good questions about how we read difficult texts, who gets to access academic ideas, and the role of academic and plain language in and around the academy:
The move from a structuralist account in which capital is understood to structure social relations in relatively homologous ways to a view of hegemony in which power relations are subject to repetition, convergence, and rearticulation brought the question of temporality into the thinking of structure, and marked a shift from a form of Althusserian theory that takes structural totalities as theoretical objects to one in which the insights into the contingent possibility of structure inaugurate a renewed conception of hegemony as bound up with the contingent sites and strategies of the rearticulation of power.
This was my era in college, and I remember feeling challenged and overwhelmed as an undergrad trying to read theory for the first time. So today, I asked Claude.ai to put it in plain language, just to see what would happen. Here’s the after:
Scholars used to think that capitalism shaped society in consistent, predictable patterns. But newer thinking focuses on how power works—how it repeats, overlaps, and gets reshaped over time. This brought time into the picture and moved away from older theories that treated social structures as fixed. Instead, recognizing that structures can change opened up a new way of understanding power: it's tied to specific moments and strategies, and it's always being renegotiated.
French overlooks how smartphones and social media raised the stakes on debate and discussion, transforming campus discourse. Today’s students worry that one viral misstep (in countless directions) may define them forever.
Connected Places uses ICE as a case study to explore trust, safety, and community dynamics on decentralized social networks, examining how federation changes community moderation expectations we’ve developed from centralized platforms.
Tiktok is not much better or worse than other major social platforms, I say. The primary arguments against TikTok, including data collection, algorithmic manipulation, potential foreign government access, addiction and influence on public opinion, apply with equal or greater force to American platforms. Meta has faced billions in fines for allowing privacy violations, enabled documented election interference, and its algorithms have been linked to mental health harms and the amplification of extremist content globally, including perpetuating a genocide in Myanmar. Google and other domestic platforms vacuum up vastly more user data with fewer restrictions.
The distinguishing factor isn’t the behavior but the ownership: TikTok’s parent company ByteDance is subject to Chinese law and intelligence relationships, while Meta and Google are subject to U.S. law and intelligence relationships. That’s a legitimate policy distinction, but rarely articulated honestly. Instead, the debate has been framed around purportedly unacceptable harms that American tech companies perpetrate routinely, creating a kind of security theater that lets domestic platforms escape equivalent scrutiny while positioning a foreign competitor for a forced sale or ban.
The TikTok deal means American users will see a US-only algorithm. Brands and creators will likely see smaller audiences and higher costs for domestic reach. ByteDance faces split algorithms, divided workforces and parallel governance, complicating product delivery across global markets.
Reading this blog post by a political scientist explaining the problem with our fractured information landscape, and how calls for more information and media literacy are not likely solutions:
“In short, decades of research have demonstrated that our political beliefs and behavior are thoroughly motivated and mediated by our social identities: i.e., the many cross-cutting social groupings we feel affinity with. And as long as we do not account for this profound and pervasive dependence, our attempts to address the epistemic failures threatening contemporary democracies will inevitably fall short. More than any particular institutional, technological, or educational reform, promoting a healthier democracy requires reshaping the social identity landscape that ultimately anchors other democratic pathologies.”
As always, this drives me back to Haraway’s cyborg, a useful metaphor for thinking about our political, environmental and social tangle and how it butts up against emerging tech and science. (In Haraway’s context, it was the rise of STEM as a driving force in academia at the dawn of the computer age.) Bagg’s argument lands in familiar territory for anyone who’s wrestled with the cyborg metaphor. Both reject the assumption that better information alone will save us from ourselves, whether from context collapse or the dualisms (binaries, heh) that structure how we think about technology, nature, humanity and politics.
Bagg arrives at something parallel from political science: We trust information that affirms the groups we belong to.
The problem isn’t that people lack access to truth, it’s that they’ve lost affinity with the experts, institutions and collaborative practices that produce real expertise. We’re arguably in era so thick with marketing that we are locked into performing respectability and purity aesthetics as our primary approach to the world and one another, instead of prioritizing social health and good function.
Both perspectives point toward the same conclusion: you have to recognize shared affinities through the slow work of creating conditions where people want to trust each other across differences.
The CEO of Instagram says that social media platforms will be under mounting pressure to help users tell the difference between human-made and AI content, and that going forward, it will be more practical to label real content over AI.
I suspect these three trends are connected: Women reportedly use AI at significantly lower rates than men—25 percent lower on average—in part because they’re more concerned about ethics, including privacy, consent and intellectual property. At the same time, countries with more positive social media experiences tend to be more open to AI, while Americans’ distrust is shaped by years of watching tech platforms erode trust. Meanwhile, one of the largest social platforms has turned its AI chatbot into a harassment tool—generating roughly one nonconsensual sexualized deepfake image per minute, disproportionately targeting women and girls.
When platforms enable abuse at scale, it makes sense that people most likely to be harmed would be most attuned to ethical concerns, and would thus be the most cautious about AI adoption.